
DAU/MAU is a compact stickiness signal that summarizes how often monthly users return on a given day; this note gives a practical measurement approach, directional benchmarks, and a realistic 1- to 6-week playbook to test lifts. Expect directional signals in 1-2 weeks for onboarding fixes and 4-6 weeks for habit changes, but timelines depend on instrumentation quality, segment sizes, and team bandwidth. Tradeoffs include engineering time, campaign spend, ARPU vs retention impacts, and privacy/consent constraints that may limit targeting or measurement.
Early proof block
| Band | DAU/MAU range | Minimum sample guidance | Quick experiment |
|---|---|---|---|
| Baseline | 5% - 15% | ~1k MAU | 7-day onboarding funnel audit (time-to-first-value) |
| Momentum | 15% - 30% | 2k - 4k MAU per segment | Segmented lifecycle campaign with 14-day holdout |
| Habit | 30% - 60%+ | 1k+ DAU for fatigue signals | 2-week notification frequency A/B test measuring churn and ARPU |
What this means: DAU/MAU compresses retention into a quick operational metric you can act on. Use the band to prioritize diagnostics and run one targeted experiment before committing more resources. Business impact: onboarding fixes are typically fastest and lowest cost; scaling lifecycle campaigns requires ROI discipline; habit products need fatigue controls to protect monetization.
How Much Money Do Indie Apps Actually Make in 2026? goes deeper on the ideas above and adds concrete next steps.
What do DAU/MAU bands indicate and how should you act?
Category: Early proof
Statistic: 5 - 15%
Label: Baseline DAU/MAU band
Context: Use only if ≥1k MAU to reduce noise
Category: Growth
Statistic: 15 - 30%
Label: Momentum DAU/MAU band
Context: Segment and iterate across 2 - 4k MAU cohorts
Category: Retention
Statistic: 30 - 60%+
Label: Habit DAU/MAU band
Context: Run fatigue + ARPU tests as usage intensifies
Use the band to decide whether to fix onboarding, optimize lifecycle, or protect monetization; each band has one prioritized experiment you can run immediately. Below are concise actions and interpretation.
Benchmark bands (directional)
Baseline (~5 - 15% DAU/MAU)
Action: run a 7-day funnel audit for time-to-first-value and D1/D7 leaks. Minimum stable sample ~1k MAU; below that expect high noise and longer test windows.
Momentum (~15 - 30% DAU/MAU)
Action: run segmented lifecycle campaigns with randomized holdouts and a 7-14 day evaluation. Require 2k - 4k MAU per segment for directional confidence.
Habit (~30 - 60%+ DAU/MAU)
Action: treat as daily habit and run a 2-week randomized frequency test measuring churn and ARPU per active user. Monitor fatigue; benefits often taper with higher touch.
Interpretation: Baseline calls for onboarding fixes; Momentum is about scaling with ROI guardrails; Habit requires protecting ARPU and customer experience. One practical caution: many early lifts decay by day 14, so include persistence checks before rollout.
How to act on the bands this week
- Baseline: if D1 < 25% and DAU/MAU < 10%, start an onboarding A/B within 7 days. Typical effort: 20-80 engineer-hours and 1-2 analyst days to instrument and analyze.
- Momentum: reserve ~10% of sends as holdout for 14 days, measure incremental ARPU vs control before scaling. Expect 1-3 analyst days to set up and 10-40 engineer-hours to integrate.
- Habit: run small frequency-cap tests for 2 weeks; revert if ARPU per DAU falls or uninstall/support spikes exceed thresholds below.
When you move from outline to execution, The Psychology Behind App Designs That Keep Users Coming Back helps close common gaps teams hit here.
How do you calculate and validate DAU/MAU?
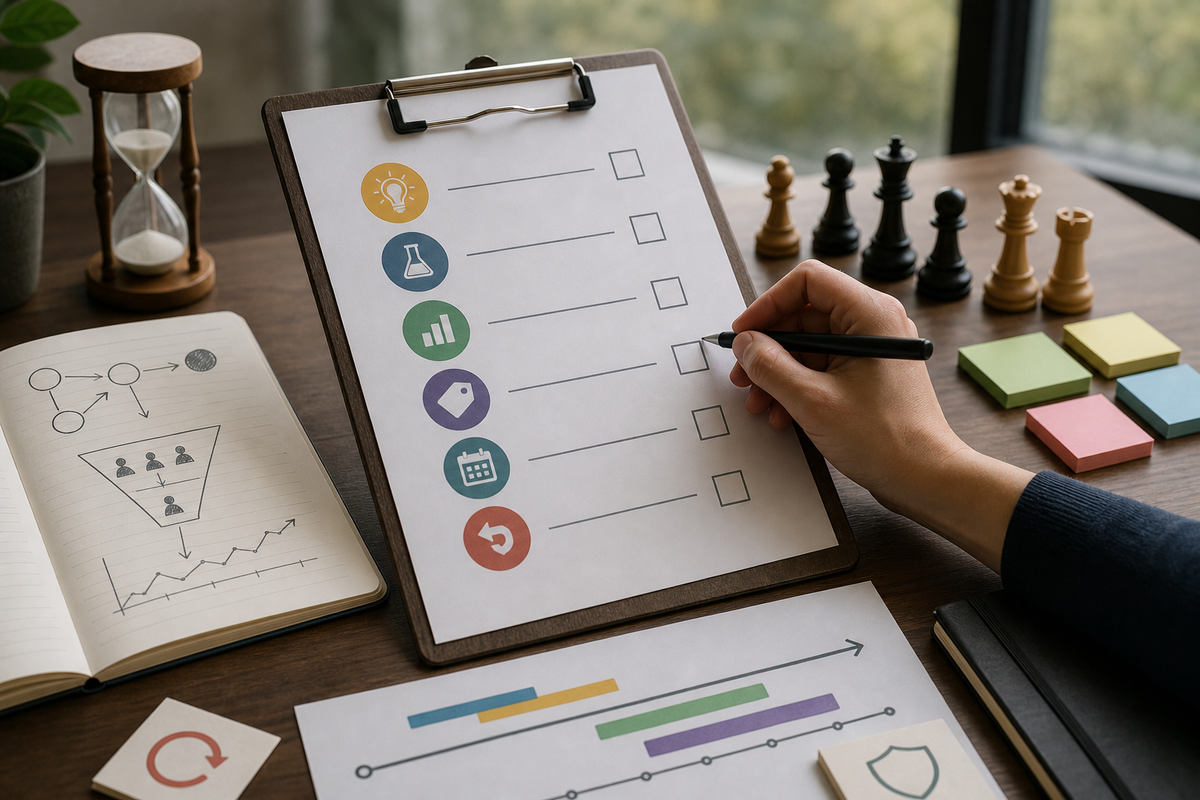
*A checklist for running an onboarding A/B test: hypothesis statement, experiment_id and sample-size target, KPIs (D1, day-14 cohort DAU/MAU), data tags required, analysis window, and explicit rollback rules (D7 fail, novelty fade, instrumentation alerts).*Calculate DAU/MAU consistently, validate identity, and annotate exports before acting on small changes. Run a short audit to decide if you can trust the signal.
Formula, window selection, and export checklist
Use DAU/MAU = unique users with an event on a UTC day ÷ unique users with at least one event in the trailing 28 or 30 days; pick one and keep it consistent.
Rolling DAU/MAU export
Export a rolling series covering the last 30 days with your chosen window tag.
Retention cohorts
Export D1 and D7 retention for the last 6 daily cohorts to spot early leaks.
Session and engagement metrics
Export sessions per user/day, median session length, and top event counts.
Annotation fields
Include experiment_id and marketing_campaign tags; flag campaign days and exclude or annotate them in trend analysis.
Event and user filters
Filter test accounts, bots, and the top 1% by event volume to reduce noise.
Timeline snapshot you can run in two weeks:
- Day 0: one-hour audit - export rolling DAU/MAU and cohort tables.
- Days 1-7: run D1/D7 checks for recent cohorts and flag deltas.
- Days 8-14: compare app-open DAU vs meaningful-action DAU and lock window choice.
Identity hygiene, dedupe, and event-based validation
Aim for >= 90% of activity mapped to a stable user_id; below 90% expect noisy DAU/MAU and plan identity reconciliation (typical effort 1-4 weeks). Dedupe test accounts and top-volume users. Trigger an instrumentation audit if DAU/MAU shifts > 5 percentage points after filtering. A gap > 40% between app-open and meaningful-action DAU often signals session inflation.
Sample-size and uncertainty
For directional trends, 1k MAU gives basic stability; to detect a +3 to +5 percentage point absolute lift, plan for 10k+ MAU or run a simple power calculation (baseline rate, target lift, alpha 0.05, power 0.8). Detectable effect size depends on variance and allocation; smaller apps may need longer windows or larger pooled segments.
Mid-article: Get the one-hour DAU/MAU audit checklist
The audit tells you whether the signal is clean for quick experiments or if you need an instrumentation sprint first.
A complementary angle worth comparing lives in Why AI App Builders Fail at the Finish Line.
How can you lift DAU/MAU in 2-6 weeks and when should you rollback?
You can run structured experiments with clear rollback rules in 2-6 weeks, but outcomes depend on instrument quality, sample size, and team bandwidth.
Prerequisites, team, and timelines
Minimum tooling: clean user_id mapping, 30-day event export, experiment platform, and campaign annotation. Team: 1 analyst + 1 product owner + 1-2 engineers for 1-3 weeks for onboarding tests; habit work may need 4-12 weeks and more staff. Engineering-hours: onboarding tests 20-80 hours; habit/frequency experiments 80-320 hours. Expect a 30-60% soft failure rate for early hypotheses; plan for follow-up iterations.
1 - 3 week onboarding experiments (tests and measurement rules)
Remove one onboarding step
A/B test removing a single screen or field. KPI: D1 retention and 14-day cohort DAU/MAU. Sample target: 10k MAU for medium apps. Measurement window: 14 days. Roll back if D7 shows no improvement or novelty fades.
First-success checklist
Add a tracked 'first success' event and guide users to it. KPI: day-0 to day-3 active rate and session quality. Require clean instrumentation for the event.
Micro-copy and contextual tooltips
Single-variable copy tests around the critical action. KPI: D1 lift and session depth. Measure 7-14 days and revert if D7 shows no lift or support tickets rise.
Operational checklist: annotate experiment_id and campaign tags, schedule a mid-test instrumentation health check, reserve a control holdout, and define rollback steps (disable feature, stop campaign, reroute traffic).
Monitoring triggers and rollback thresholds
Use concrete thresholds and clear owners.
- Auto-alert if D1 or D7 drops > 5 percentage points versus baseline.
- Alert if uninstalls per 1k DAU increase > 2 absolute or relative increase > 50%.
- Alert if support tickets per 1k DAU increase > 5.
Ownership: send alerts to the product incident Slack channel; product owner evaluates within 2 hours and engineering on-call should execute rollback within 4 hours. These are conservative defaults; adjust to your SLA and risk tolerance.
One caution: a welcome modal we tested boosted D1 by 6 points but reverted by day 14 and increased support volume; we rolled it back and reworked the flow.


